AI inference economics, inside your boundaries.

your models + data
servescale.aiprivate inference platform
CloudColoOn-prem
power · cost · performance

Ease of an inference service + Control of the enterprise stack. Not another API endpoint.

servescale.ai helps IT organizations offer cost-effective inference and model-hosting services across cloud, colo, and on-prem infrastructure - with enterprise control, predictable budgets, and unmatched cost efficiency and performance.

60%+Inference cost reduction. Continuously optimized for your environment. No need for high-end AI datacenters. Compatible with your enterprise budget processes.
Any environmentPublic cloud, private cloud, colo, on-prem, neocloud, edge. Hardware agnostic. Multiple simultaneous inference runtime support. Fully multitenant.
Your assetsYour models, data, infra. Inside your perimeter. We'll make it work within your boundaries, under your control.

Host, operate + scale

Run your value-added models safely. Leverage your data moat. Control your inference cost. Inside your perimeter.

Analyze

Understand workload, model, and available infrastructure.
Optimize

Transform the workload/model to match the infrastructure.

Economic
control plane

Observe

Watch performance, learn, and adapt continuously.

Deploy +
scale

Use and optimize resources where available.

Optimized for your models on your infrastructure: power, cost, performance

Economics-first private inferenceplatform your IT teamcan actually operate andtrust.

servescale.ai's software solution fuses optimized model serving, routing, caching, virtualization, and operational controls into a self-hosted software platform designed to power your distributed enterprise inference cloud, and model hosting services.

Explore the servescale.ai product
Input

Your models

Open-weight, custom, domain-specific LLMs and SLMs. Augmentation, context engineering. Full control over deployment, updates, context, and operations.

Runtime

Your infrastructure

Public cloud, neocloud, colo, on-prem, edge - any combination. Heterogeneous GPUs, CPUs, NPUs, xPUs, virtualized and scheduled without scale-up dependence. In your Kubernetes.

Outcome

Your economics

Predictable budgets instead of uncontrolled per-token spend. Lower ops and infrastructure costs. We monetize waste reduction, not capacity consumption.

One platform. Four ways to put private inference to work.

Start with the operating need. Keep the same governed model service underneath.

01

Agentic AI

Run multi-step agents across models, tools, and enterprise context under one policy and service layer.

Explore
02

Enterprise Model as a Service

Publish approved models behind stable APIs with shared capacity, tenant controls, and predictable service levels.

Explore
03

Sovereign AI

Operate inference within regional, organizational, and infrastructure boundaries you control.

Explore
04

Data sovereignty

Keep proprietary models, enterprise context, cache state, and operational data inside the required perimeter.

Explore

An operating system for your distributed enterprise inference cloud.

with model-aware resource management, virtualization, context management, and economics-first scheduling
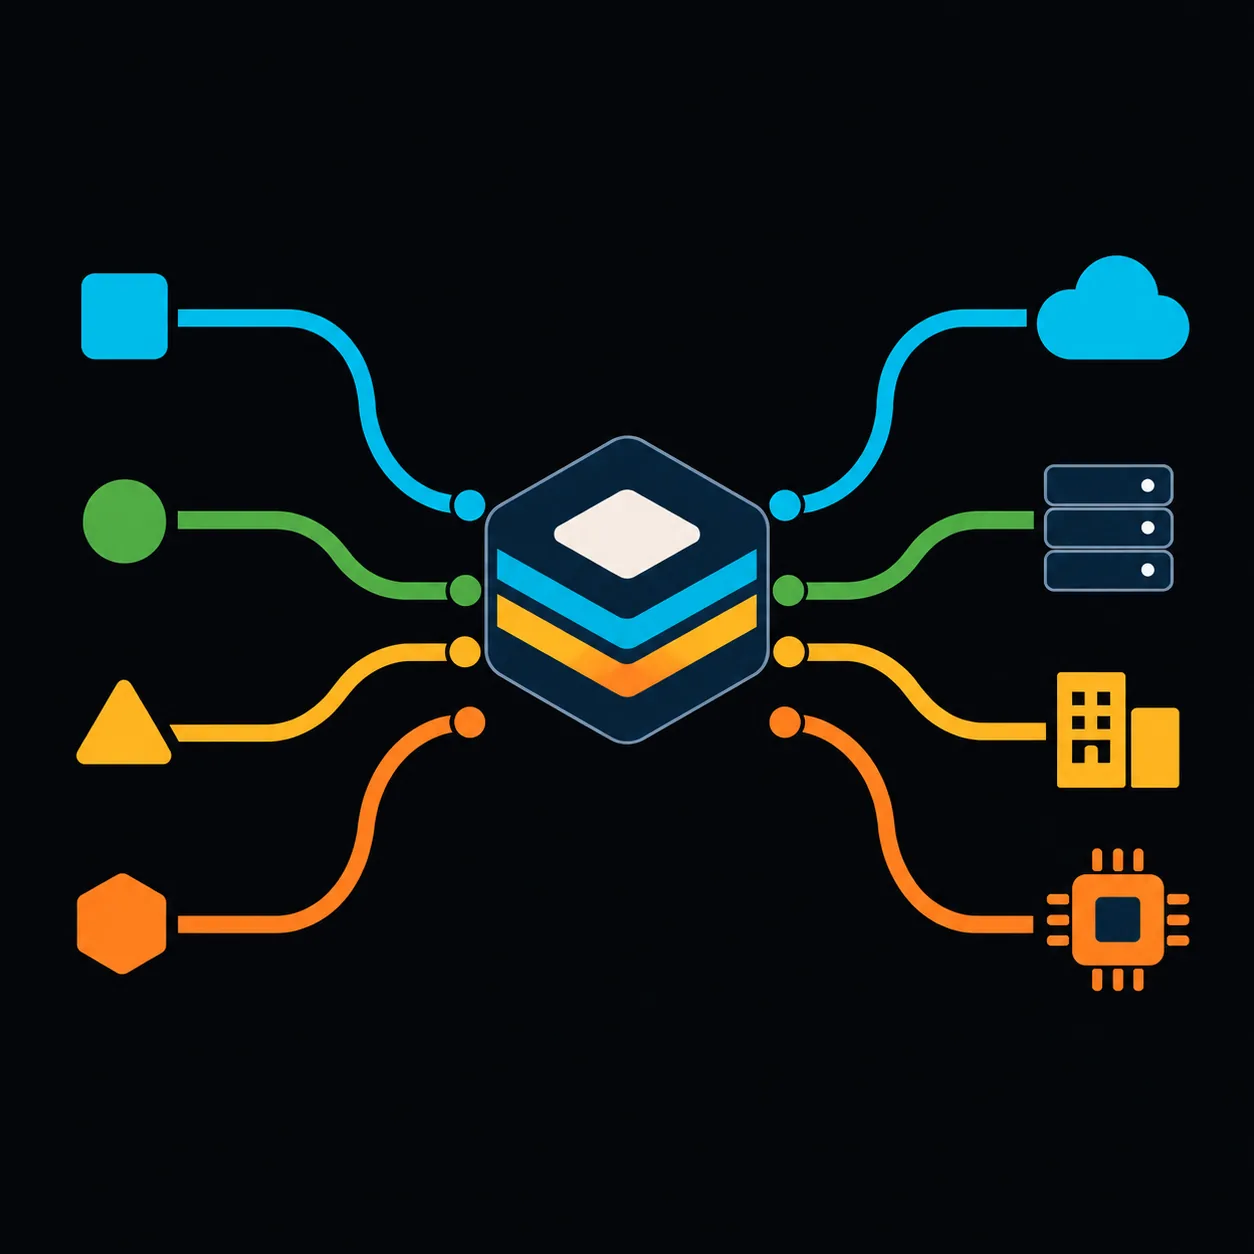
  • Model serving with multiple concurrent inference runtimes, data augmentation, and context management
  • Model-aware resource management and dynamic scheduling
  • Infrastructure- and hardware-agnostic deployment
  • Multi-tenancy via GPU, CPU, and memory virtualization with SLA/SLO support
  • Single server to hundreds of racks; federatable across private, public, and neocloud environments
Standard APIs + MCP
Model analyzer
Model optimizer
Model-aware scheduler
Router
Cache plane
Runtimes
Virtualization + multi-tenancy
Your infrastructureK8s · compute · storage · network · xPUs
Your cloudPrivate · colo · neocloud · public cloud

Economics-first, model- and topology-aware inference.

The system adapts models to infrastructure and continuously optimizes execution.

Learn more
Model adaptationQuantize, prune, shard, on-the-fly kernel recompile, test, rollback, and run A/B deployment scenarios. Continuously tune hardware, runtime and caching parameters based on observations.
Dynamic schedulingModel- and topology-aware scheduling with automatic sharding and continuous optimization. Virtualized GPU, NPU, and CPU resources.
Split prefill / decodeSupport for disaggregated execution and CPU spill for decode when economics make sense.
Fast KV-cacheDistributed, tiered, virtualized KV-cache for more efficient serving under enterprise constraints. Automatically tuned per model metadata.
Inference runtimesMultiple simultaneous inference runtimes picked to best suit the model, given the user’s performance and cost constraints. Parameters and configuration are continuously tuned to achieve ultimate performance.
Automated recoveryRuntime designed for resilience, rollback, and operational continuity.
model analyzer + optimizer + scheduler + virtualization =
the economic control plane

Watts → ROI. Optimized.